

The global AI ecosystem is shifting from a single innovation network jointly supported by U.S. closed-source models, Nvidia compute, American cloud platforms, English-language internet data, and open-source communities into a multi-centered ecosystem divided by national security, model access rights, data sovereignty, compute adaptation, and post-training systems.
This essay is part of the series of China AI System.
The previous three essays discussed a structural shift: the United States is bringing AI capability leakage into the national security perimeter, China is being forced to build its own AI production system, and the global AI ecosystem is entering a dual-track structure. The release of DeepSeek V4, especially its adaptation to Huawei Ascend, provides a concrete real-world case. For the first time, it allows us to see more clearly that China’s AI self-bootstrapping system is not an abstract slogan. It is beginning to form specific connections among models, cost, open source, domestic compute, and private deployment.


DeepSeek V4 quickly hit several sensitive points in overseas technology media: performance, price, open source, and Huawei Ascend. Bloomberg focused on its challenge to OpenAI and Anthropic. Reuters placed direct emphasis on V4’s adaptation to Huawei Ascend chips. AP also discussed the release of V4 in the context of China-U.S. technology competition and American accusations of “model extraction.” In other words, what overseas observers really saw was not an ordinary model update, but a combined signal: a Chinese model, domestic compute, and an open ecosystem appearing at the same time.
This is what truly worries the American technology establishment: once Chinese models first form a mature deployment path around domestic compute platforms, the ecosystem control that America has long maintained through Nvidia/CUDA and closed-source models will be weakened.
The focus of this essay is not to decide whether DeepSeek V4 has already fully surpassed GPT-5.5, Claude Opus, or Gemini. Nor is it meant to be a simple model review. What really matters about DeepSeek V4 is that it places several previously scattered elements onto one path: open weights, low-cost inference, million-token context, strong coding and reasoning capability, the possibility of private deployment, and adaptation to the Huawei Ascend/CANN system.
This is not proof that China AI has already achieved full self-sufficiency. It is better understood as an early but clear signal: China AI is moving from single-point model catch-up toward system-level coordination among models, chips, software stacks, open-source ecosystems, and private deployment.
In other words, the greatest significance of DeepSeek V4 is not merely that “another strong model has been released.” Its real significance is that it makes China’s AI self-bootstrapping system feel concrete for the first time. In the past, discussions of China AI autonomy easily remained fragmented across chips, models, data, and cloud platforms. But V4’s adaptation to Ascend connects these layers. It allows us to see a new question more clearly: if America restricts China from extracting capabilities from closed-source models, can China use its own open models, domestic compute, and low-cost deployment path to build an AI production system capable of continuous self-iteration?
I. The Real Significance of DeepSeek V4 Is Not Another Model Release, but the Combination of Open Weights, Low Cost, and Long Context
The release of DeepSeek V4 is first and foremost a model event. According to DeepSeek’s official release note, DeepSeek-V4 Preview has been launched and open-sourced, with two versions: DeepSeek-V4-Pro and DeepSeek-V4-Flash. V4-Pro has 1.6T total parameters and 49B active parameters, while V4-Flash has 284B total parameters and 13B active parameters. Both support 1M context length. DeepSeek officially describes this as a new stage of “cost-effective 1M context length.” The Hugging Face page also shows that the DeepSeek-V4 series includes two MoE language models: the Pro version with 1.6T parameters and 49B active parameters, and the Flash version with 284B parameters and 13B active parameters. Both support million-token context.
From the product structure, the division between V4-Pro and V4-Flash is clear. Pro is aimed at more complex tasks, especially agentic coding, competitive programming, complex reasoning, and difficult engineering problems. Flash is designed for faster, cheaper, and more economical large-scale usage. Reuters’ coverage of V4 also noted that V4-Pro performs better on complex tasks, while Flash is faster and more cost-efficient but weaker on complex tasks. The report also emphasized that V4’s 1-million-token context window and its architecture for reducing compute and memory costs are important features of the release.
The significance of 1M context is not just a number on a specification sheet. It means the model can process extremely long codebases, long documents, long conversations, complex project materials, enterprise knowledge-base fragments, and multi-turn task histories within a single context window. For many real applications, the bottleneck of model capability is not only “can it reason?” but also “can it see enough context?” If a model can only see fragmented information, it becomes difficult to truly complete enterprise document analysis, codebase understanding, compliance review, research material organization, or complex agent workflows. V4’s million-token context pushes DeepSeek more clearly toward long-document, codebase, and enterprise application scenarios.
Early developer feedback has also concentrated in similar areas: long context, codebase processing, pricing, and high-frequency usage. Some Reddit and X users have treated V4’s long-text processing capability as its most direct practical value, especially for large codebases, long documents, and high-frequency automation tasks. However, these reactions still belong to the first wave of user experience and cannot replace independent benchmarks or enterprise-grade stability validation.
But the more important issue is cost structure. DeepSeek V4’s impact comes not only from capability, but from the combination of capability and cost. The Pro/Flash dual-track structure itself shows that DeepSeek is not merely pursuing a single highest-scoring model. It is trying to build a model system with different cost tiers. High-performance models can handle complex tasks, while low-cost models can handle high-frequency calls and large-scale deployment. For SMBs, research institutions, educational settings, individual developers, and small-to-medium SaaS teams, this kind of model is not merely “one more option.” It may release part of frontier-level capability from the high-price regime of a few closed-source giants.
From public pricing, this cost difference is very direct. DeepSeek V4-Pro is priced at roughly $1.74 / $3.48 per million input/output tokens, while V4-Flash falls further to around $0.14 / $0.28 per million input/output tokens. By comparison, OpenAI GPT-5.5 API pricing is roughly $5 / $30 per million input/output tokens, while GPT-5.5 Pro is higher, at around $30 / $180; Claude Opus 4.7 is around $5 / $25. This means that on output tokens, which are more expensive and more directly affect agent and code-generation costs, V4-Pro is roughly just over one-tenth of GPT-5.5’s cost and about one-seventh of Claude Opus 4.7’s cost. V4-Flash pushes output costs even lower, down to roughly the one-percent range of top American closed-source models.
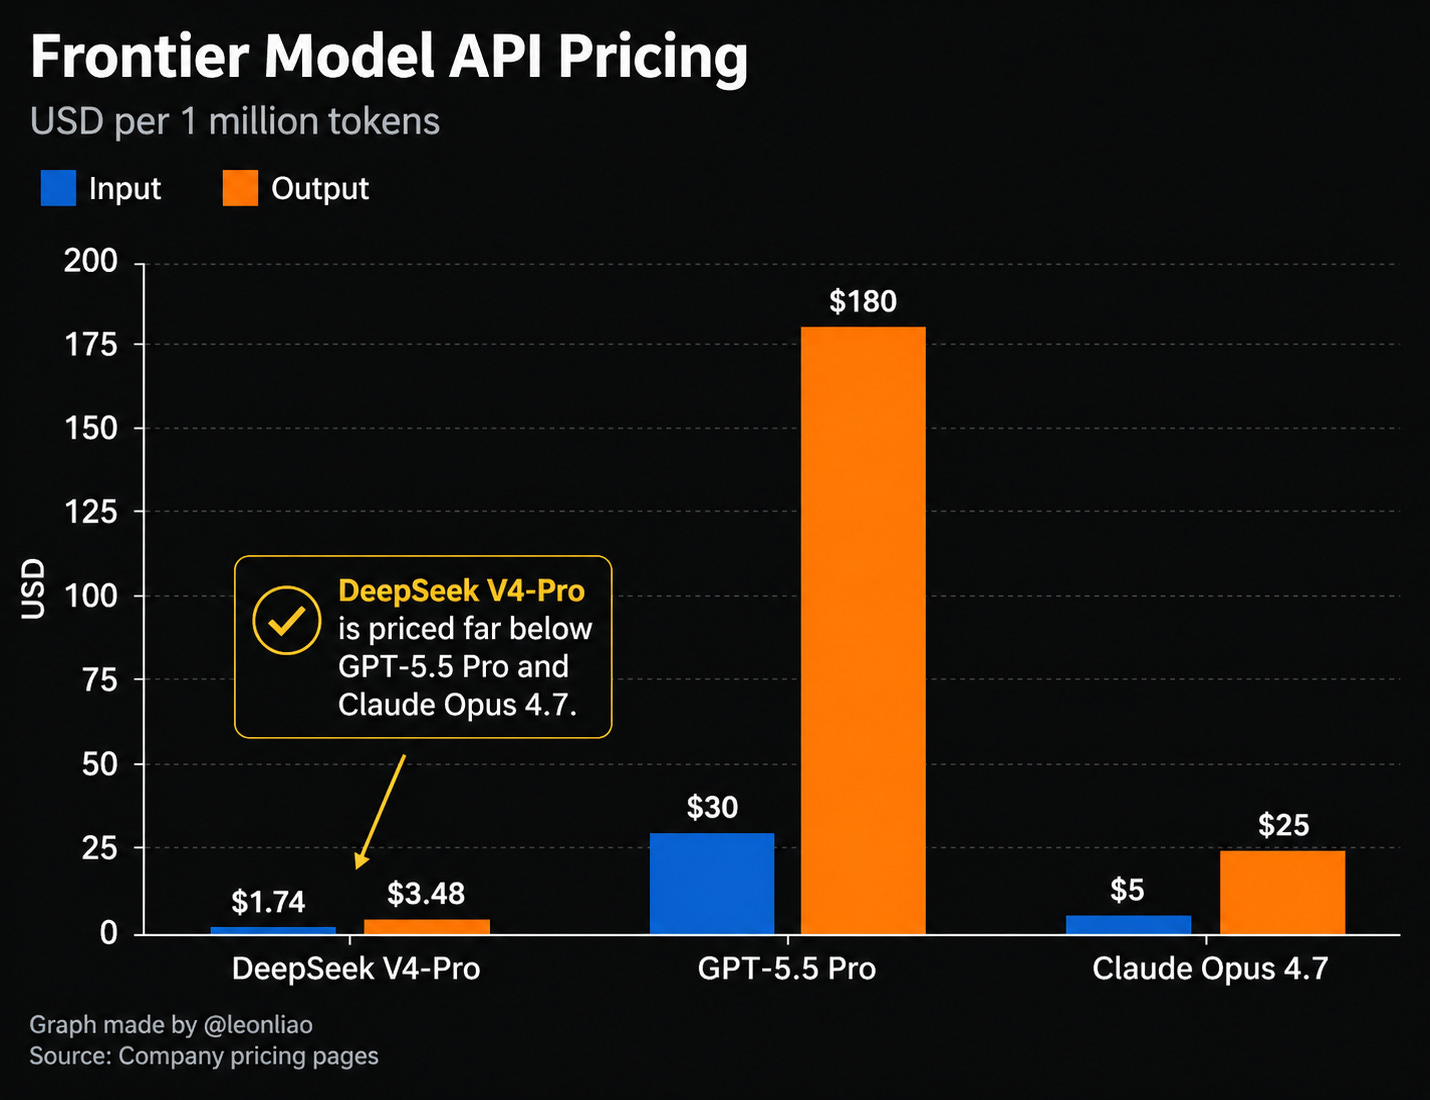
This is not an ordinary price discount. It is a revaluation of AI application economics. For long context, code generation, enterprise document processing, educational tutoring, research assistants, and high-frequency agent workflows, what determines whether a system can be deployed at scale is often not the highest capability of a single call, but the total cost per task. If a model’s capability is already close to part of the frontier closed-source model range, while its output price is only a fraction, or even one percent, of the latter’s price, then many AI workflows that previously existed only as demos begin to gain real commercial feasibility. This is the most disruptive part of V4: it does not merely sell the model cheaply. It pulls near-frontier capability out of the high-margin closed-source API system and back onto a lower-cost, more deployable engineering path better suited for private deployment and large-scale usage.
V4’s low cost is not simply a price war. It is tied to long-context architectural optimization. Hugging Face’s technical interpretation of V4 noted that V4’s efficiency gains come from hybrid attention: CSA and HCA, two attention mechanisms, are interleaved across different layers, reducing compute and memory pressure under million-token context. DeepSeek-related mHC research proposes Manifold-Constrained Hyper-Connections, which restore the identity mapping property through manifold projection of residual connection space, while combining infrastructure optimization to improve stability at training scale.
This is also where the DeepSeek route has always been most disruptive. The advantage of America’s top closed-source models lies in capability ceiling, ecosystem maturity, enterprise compliance, and multimodal toolchains. DeepSeek’s advantage lies in placing near-frontier capability onto a lower-cost, more open, and more privately deployable path. Reuters also placed DeepSeek V4 in the context of China reducing dependence on foreign AI technology and building a self-sufficient ecosystem, saying that its release strengthens China’s pursuit of AI autonomy.
This brings us back to the central theme of this series. America’s effort to restrict Chinese distillation of closed-source models is, in effect, an effort to restrict China from cheaply learning capabilities from American model outputs. If China can only rely on American closed-source models as teachers, then its catch-up path will naturally be constrained by American platforms, APIs, service terms, and national security boundaries. The significance of DeepSeek V4 is that it offers another possibility: China’s own strong models can become open teacher models, allowing developers, enterprises, and research teams to distill, fine-tune, privately deploy, and build on top of them.
A boundary needs to be emphasized here. DeepSeek V4 is not a complete replacement for the highest-end closed-source models. In ecosystem maturity, multimodal capability, long-horizon agent execution, and enterprise-grade product stacks, it still cannot be simply equated with the latest closed-source models from OpenAI, Anthropic, or Google. But it may become a capability repricing event within the open model ecosystem. Its core is not “making the strongest model in the world,” but placing quite strong capability onto a lower-cost, more open, and more deployable engineering path.
This is the first layer of DeepSeek V4’s significance: it is not only competing on model leaderboards. It is changing the cost curve and accessibility of frontier-level capability.
II. Ascend Adaptation Is the Bigger Signal: China Is Beginning to Push Model-Chip-Software Stack Co-Optimization
What truly worries the American chip industry is not that a single Chinese model is getting stronger. It is that Chinese models are beginning to form deployment paths around domestic compute platforms first.
If we only look at model parameters, context length, and API pricing, DeepSeek V4 is already worth paying attention to. But within the broader context of the great partition of the global AI ecosystem, its most important signal is its adaptation to Huawei Ascend.
Reuters reported that DeepSeek V4 is DeepSeek’s latest model preview and has already been adapted to Huawei Ascend AI chips. The report explicitly stated that this move reflects China’s effort to reduce dependence on foreign AI technologies and build a self-sufficient ecosystem. Another Reuters report said that Huawei announced its Ascend supernode, based on the Ascend 950 AI chip, would fully support DeepSeek V4. The significance of this is not the simple phrase “domestic substitution.” Rather, it brings together several of the most critical layers of China’s AI ecosystem: model, chip, software stack, cluster, and deployment.
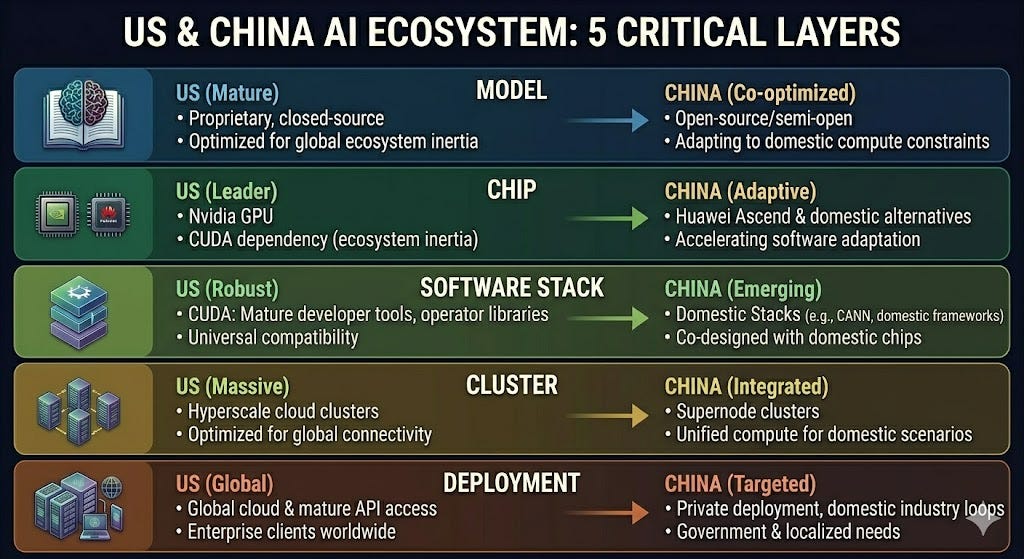
Over the past few years, the default foundation of global AI has been Nvidia/CUDA. CUDA is not just a toolkit. It is an entire set of developer habits, operator libraries, framework adaptations, inference optimizations, training schedulers, cluster experience, and ecosystem inertia. Much open-source inference code, training scripts, quantization tools, benchmark tools, and deployment solutions are built by default around Nvidia GPUs and CUDA environments. Even if China has domestic chips, the hardware itself is difficult to convert into usable compute if the software stack, operator coverage, framework adaptation, model structure, and developer toolchain do not work together.
Therefore, the real importance of DeepSeek V4’s adaptation to Ascend is not that it proves China has fully escaped Nvidia/CUDA. It proves that China is taking a substantive step toward joint optimization among models, domestic chips, and domestic software stacks. Running a model on domestic chips is only the first step. What truly matters is that future model architectures, MoE routing, long-context optimization, KV cache, low-bit inference, operator libraries, CANN compilation optimization, cluster communication, fault-tolerant scheduling, and deployment frameworks all need to be co-designed around domestic compute. Chinese models and domestic compute are beginning to enter a phase of joint optimization.
This is the most critical part of China’s AI self-bootstrapping system. Self-bootstrapping does not mean merely having a Chinese model or a Chinese chip. It means that models and chips can form a continuous feedback loop: model design understands chip constraints; chips and software stacks adapt to model structures; inference frameworks optimize real deployment; enterprises and developers discover problems in domestic environments; and those problems then push the next round of model and system improvement. Only after this loop begins can domestic compute stop being merely something that “can run” a model and start becoming part of the ecosystem.
The combination of DeepSeek V4 and Huawei Ascend gives China’s AI ecosystem a clearer demonstration of this direction for the first time. DeepSeek provides strong models, open weights, long context, and low-cost inference. Huawei provides Ascend chips, the CANN software stack, supernode clusters, and government-enterprise deployment infrastructure. Once combined, they do not produce a single isolated technology, but a new technical route: open model capability runs on domestic compute, and then enters enterprises, developers, and industry scenarios through private deployment.
This stands in sharp contrast to the American AI route. America’s strength lies in the combination of Nvidia/CUDA, hyperscale cloud clusters, closed-source frontier models, a mature API ecosystem, global enterprise clients, and developer toolchains. China cannot replicate this entire mature system in the short term. Its more realistic route is to form another combination: open or semi-open models such as DeepSeek, Qwen, GLM, Kimi, and MiniMax; Huawei Ascend and other domestic compute; domestic software stacks such as CANN; local cloud infrastructure such as Alibaba Cloud, Huawei Cloud, Baidu AI Cloud, and Tencent Cloud; and private deployment, low-cost inference, and industry data loops.
This is not an easier route. On the contrary, it is harder. The American route is already highly mature, and Nvidia and CUDA have very deep ecosystem advantages. The Chinese route needs to fill gaps in hardware, software, models, toolchains, developer ecosystems, and enterprise deployment experience at the same time. DeepSeek V4’s adaptation to Ascend does not mean these problems have already been solved. It only shows that China’s AI system is beginning to move from “each side filling its own gaps” toward “forming a stack together.”
This has major implications for global AI competition. America’s restrictions on China’s access to the most advanced chips were originally meant to compress China’s ability to train frontier models. Its restrictions on model distillation are meant to compress China’s ability to cheaply learn from American closed-source model outputs. But these restrictions also generate counterforces. They force Chinese model companies and domestic chip companies to co-adapt earlier and more deeply. In other words, the stronger the American restrictions become, the less China can base model training and inference on the assumption that it will always be able to obtain Nvidia GPUs and always be able to call American closed-source models.
So the relationship between DeepSeek V4 and Ascend should not be understood as a simple news item: “one model supports one chip.” A more accurate interpretation is: China AI is redesigning model capability, domestic hardware, domestic software stacks, and deployment needs within the same system.
This is the second layer of DeepSeek V4’s significance: it does not prove that China has fully de-CUDA-ized. It marks the beginning of China AI’s move toward model-chip-software stack co-optimization.